Machine Learning to prevent online harassment of children
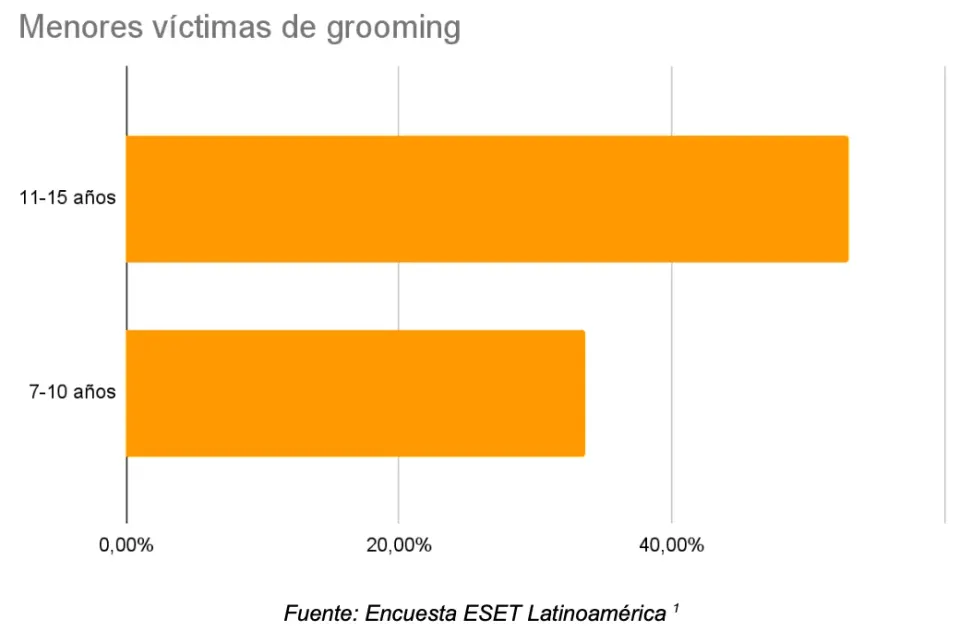
From safe navigation to the fear of losing it. When your children surf the internet, do you apply or configure any parental control filters? Latam online. Second Edition. 2021 Currently, sexual harassment or harassment…
A learning project shared by the community. The article documents its team, methods and results; it does not establish that the prototype is ready for real-world use.
This archive includes automatic translations. Audio, video and text inside images remain in their original language.
From safe navigation to the fear of losing it.
When your children surf the internet, do you apply or configure any parental control filters?
Latam online. Second Edition. 2021
Currently, online sexual harassment or harassment is known in English as online grooming; where an adult manages to have contact through a technological means against a minor, the objective of the abuser being to attack through interactions such as: harassment of their morals, talking about sex, obtaining intimate material or agreeing to a sexual encounter.
Online grooming has increased as a result of the COVID-19 confinement. In Argentina it increased more than 30% in 2020(2), INEGI data from 2019 shows that in Mexico it grew 27%(3), while the Spanish newspaper ABC reported an increase of 410% in recent years (4).
Context… please!
Current parental control applications use blocking applications, some inappropriate sites, preventing online purchases or the access of viruses to devices such as cell phones, tablets or computers of children and adolescents. However, none of them analyze conversations on social networks and neither classify those that could be classified as dangerous.
Derived from the confinement due to COVID-19, children and adolescents have been more vulnerable due to the need to use mobile devices as part of their daily activities. Much of this was to take virtual classes, complete homework and on other occasions as a means of entertainment and communication, as they were limited by not being able to go out and share time with family and friends.
Lack of supervision has allowed minors to experience unwanted situations without the knowledge of adults.
According to the health site with magnifying glass, 39% of harassment has been experienced on Facebook, followed by 23% on Instagram and 14% on WhatsApp (5).
The proposal
Totem means protector
Totem = “Let it Navigate Without Worries”
Without much fuss, this is what we did.
We currently have a dataset of conversations in English, which are analyzed and classified as normal or dangerous. Once this result is obtained, a notification will be sent to the parent or guardian if an inappropriate conversation is detected.
How did they do that?!
Here we explain what we applied to obtain the results that we will show you later...
Phase 1 (Here we go…)
Obtaining the data
The data was acquired from the PAN Lab 20126 project. The folder with the data was requested and we were granted permission to use it. Reviewing the data we found conversations of varying lengths, in which the participants had different ways of writing and the corpus file had an .xml format. Therefore, the data was converted to a .csv format, “Comma Separated Values”, in order to proceed with the next phase.
Phase 2 (Let's analyze this...)
Data Cleaning
The second task presented a high degree of difficulty, due to the noise of the data. Therefore the following steps were followed.
- Any type of punctuation was eliminated.
- Numbers were converted to words using the library num2words.
- We searched for abbreviations and texts with cyber slang such as: “u” for “you”, “ur” for “your”, “what ‘s” for “what is”, among others. In addition, a dictionary was created with these new words.
- Se eliminaron las stopwords como: the, and, that, a, any, an, be, with. Entre otras.
- Removed emojis, URLs, hashtags and any type of alphanumeric value.
- The lemmatization technique was used to bring all the verbs to their infinitive form. In order to create embeddings from simpler words.
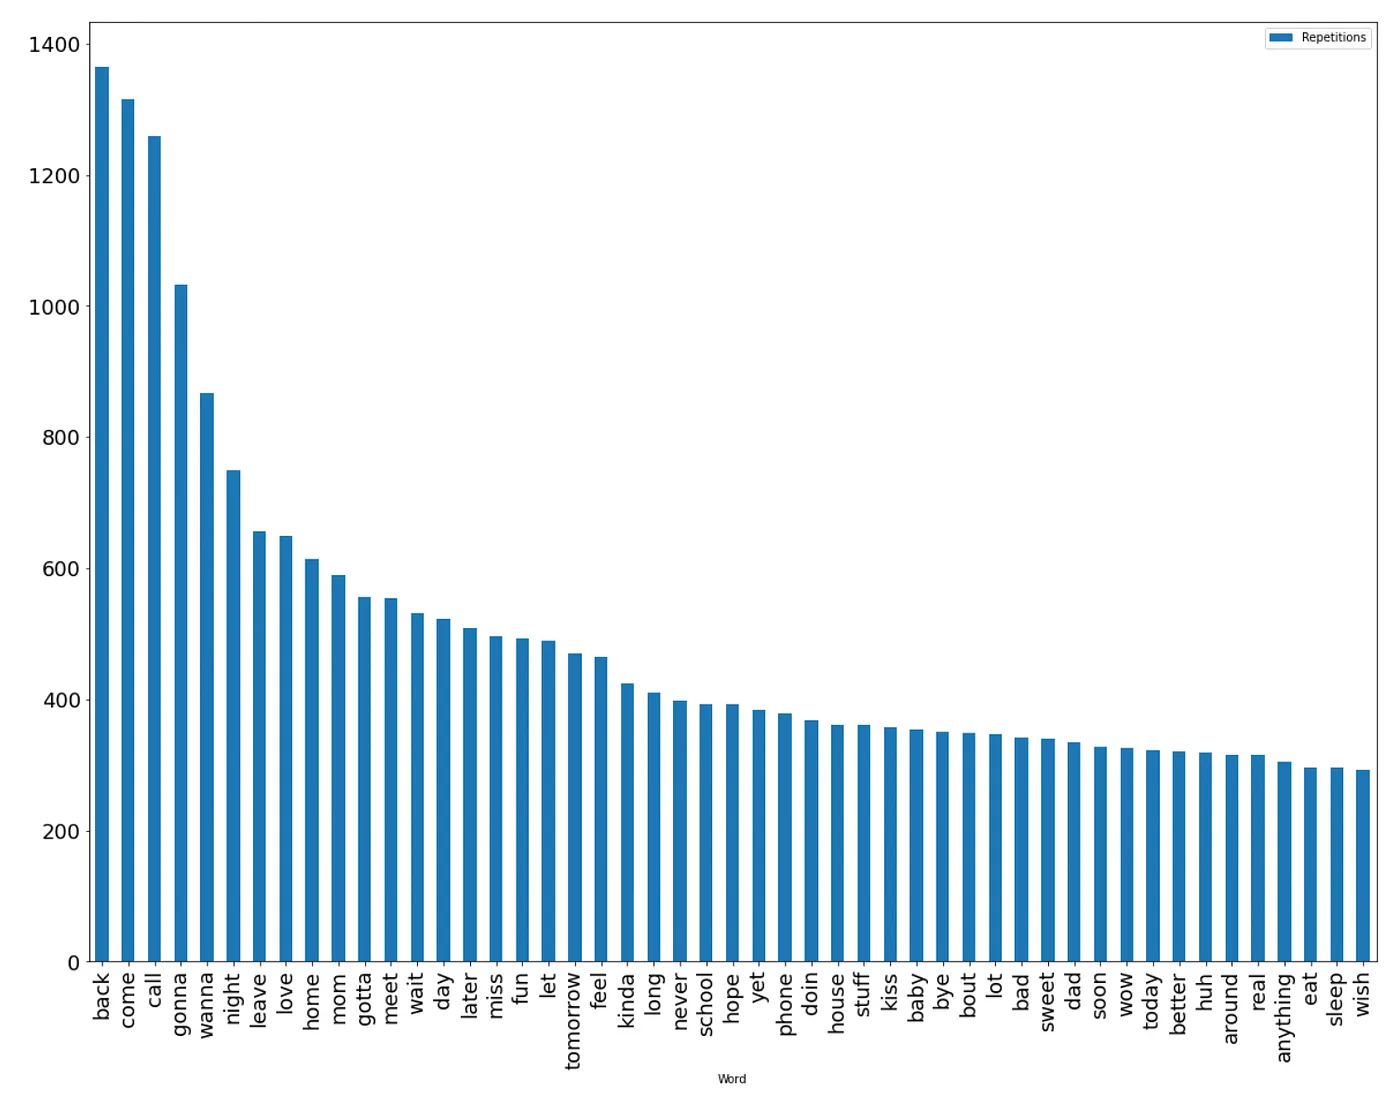
- The data was explored, analyzing the 100 most common words in the predators' conversations.
Phase 3 (Let's train this...)
Vectorization
The extraction of characteristics represented a particular challenge, in the first instance it was decided to do it based on the most frequent words present in the conversations of predators; However, several of these were in common use, so it was necessary to analyze alternatives to achieve optimal performance. Thus, it was decided to use the TF-IDF method (Term Frequency — Inverse Document Frequency), one of its characteristics being to highlight the importance of a word in a set of documents (corpus). In this sense, to transform the sequence of words (from conversations) into feature vectors with numerical representations, the TF-IDF vectorizer (TfidfVectorizer) from the scikit-learn library was used. This transformer made it possible to generate a matrix of characteristics, with an adequate representation to train the model. For this purpose, the dataset was divided into:
- Training data: 80%
- Testing data: 20%
Training
To train the model, the scikit-learn library was used and the Support Vector Machines (SVM) model was chosen to use a binary classifier.
The hyper parameters were:
- Regularization parameter ©: 10
- Kernel: RBF
- Kernel coefficient (gamma): Scale
Evaluation
During the evaluation of the model the following results were obtained:
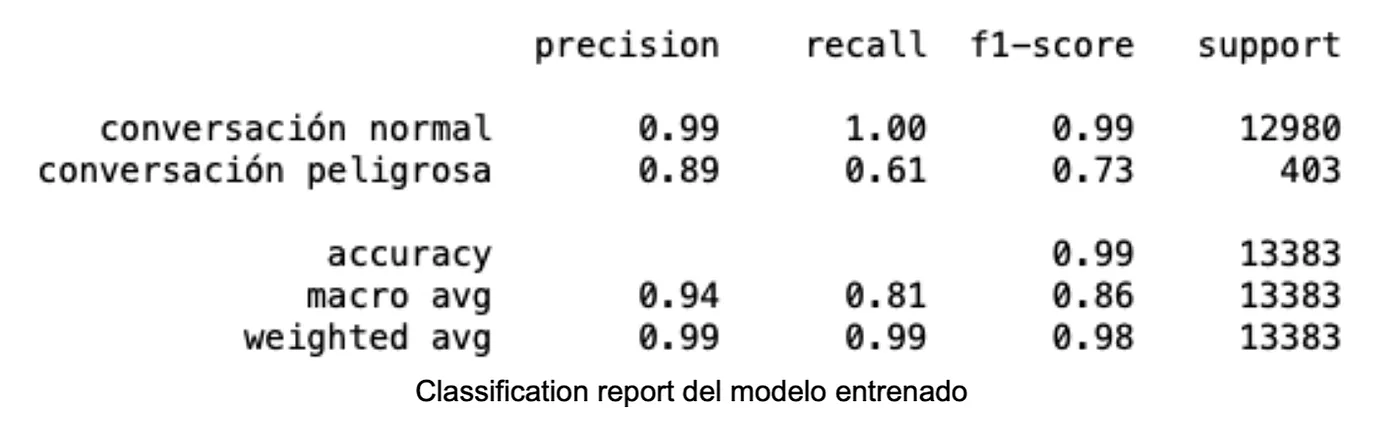
The confusion matrix being the following:
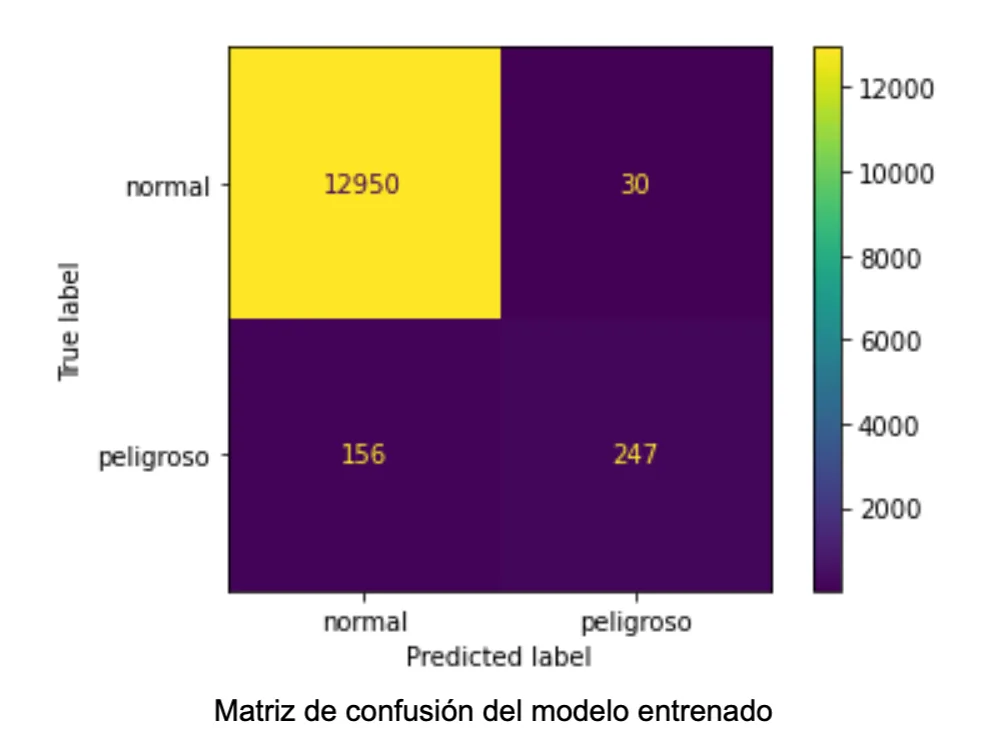
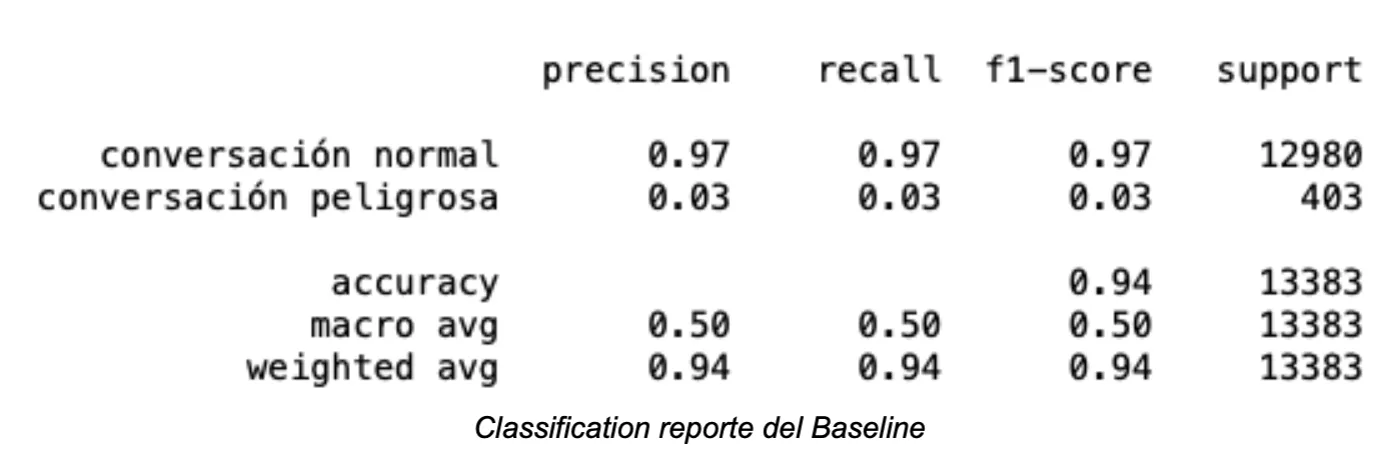
The model results show a notable improvement compared to those corresponding to the Baseline:
The developed model was deployed in a web application using the Streamlit tool, in which the conversation to be analyzed is provided through the interface and the application shows the alert if it is a normal or dangerous application. Below are some examples of its operation:
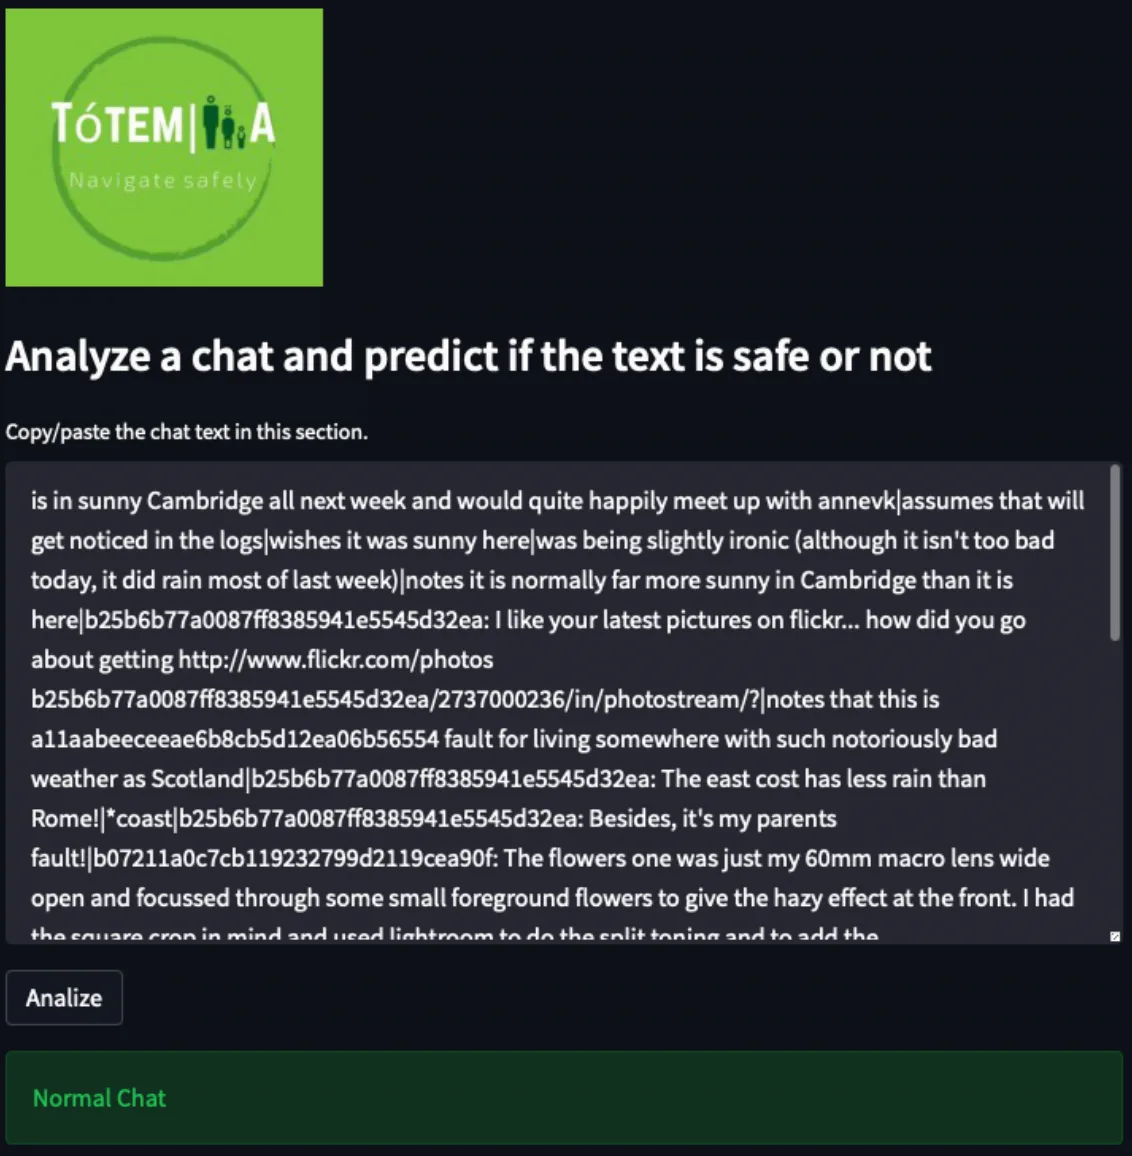
Analysis result in a normal conversation
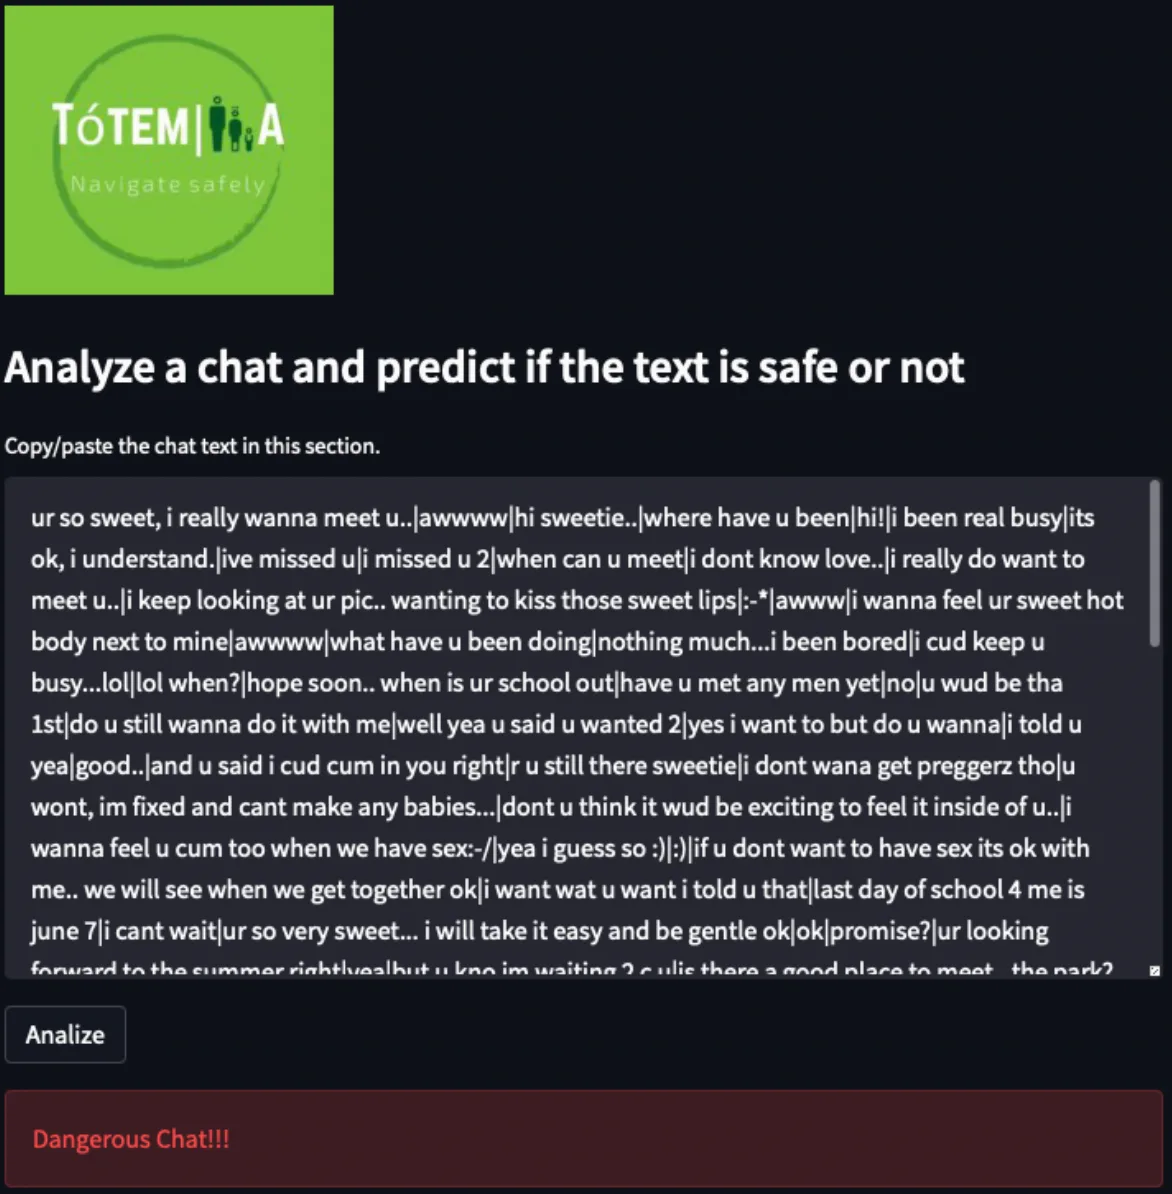
Result of the analysis of a dangerous conversation
Does our proposal make sense to you?
Until now we have been able to analyze and classify inappropriate conversations that can be reported and thus provide tools to parents for monitoring applications whose function is not to interfere with privacy but to prevent dangerous situations in online conversations.
In the future, it would be great to develop these alerts available to parents as part of the restrictions of some applications, which are concerned with applying parental control rules for vulnerable users who use their services, such as: https://www.facebook.com, https://www.instagram.com, https://www.tiktok.com, https://www.whatsapp.com, etc.
References
- http://www.eset-la.com/micrositios/proteccion-infantil/descargar/grooming_chicos_eset.pdf
- https://www.unidiversidad.com.ar/por-la-hiperconectividad-en-cuarentena-el-grooming-aumento-un-30-en-argentina
- https://alumbramx.org/ciberacoso-y-grooming-contra-ninas-ninos-y-adolescentes-en-aumento-por-covid-19/
- https://www.abc.es/familia/padres-hijos/abci-grooming-y-aumentado-410-por-ciento-ultimos-anos-201903081632_noticia.html?ref=https%3A%2F%2Fwww.google.com%2F
- https://saludconlupa.com/la-vida-de-nosotras/ninas-y-mujeres-hablan-del-acoso-en-linea/
- http://pan.webis.de
- https://www.welivesecurity.com/la-es/2020/05/20/grooming-crece-durante-cuarentena/
Here you can see a video that describes our proposal
Members
- Aaron Arguello
- Edson Segales
- Ingrid Velecela
- Karla Aviles
- Viridiana Vergara
Project presentation: DemoDay
Repository
And if you want to see the data source and the code we applied, you can find it on GitHub:
https://github.com/SaturdaysAI/Projects/tree/master/LATAM_remote/TotemIA
More artificial intelligence!
The mission of Saturdays.ai is to make artificial intelligence more accessible (#ai4all) through intensive courses and programs where projects for good are carried out (#ai4good).
If you want to learn more about artificial intelligence join our community at community.saturdays.ai or visit us on our website www.saturdays.ai Join us!
A history of the Saturdays.AI community. Originally published on March 9, 2022.
← More community stories